CVPR 2024 Workshop · Efficient Large Vision Models
Unleash the Potential of CLIP for Video Highlight Detection
* equal contribution
Abstract
Multimodal pre-trained models have unlocked open-world knowledge across many tasks; the video domain is no exception. We present Highlight-CLIP (HL-CLIP), a method designed to excel at video highlight detection by leveraging the pre-trained knowledge embedded in multimodal encoders. Simply fine-tuning the multimodal encoder together with our saliency pooling technique achieves state-of-the-art on the QVHighlights benchmark.
TL;DR
- Detector-free. No DETR head, no SlowFast features. Just CLIP with a focused fine-tuning strategy and a lightweight inference-time pooling.
- Tune the last two layers. Only the final two layers of CLIP's vision and text encoders are fine-tuned — preserving pre-trained semantics.
- Saliency pooling. At inference, average predicted saliency across neighboring frames. Robust to per-frame noise without retraining.
- SOTA on QVHighlights. 42.40 mAP / 72.42 HIT@1 on val; 41.94 / 70.60 on test — exceeding CG-DETR (40.33 mAP).
Method
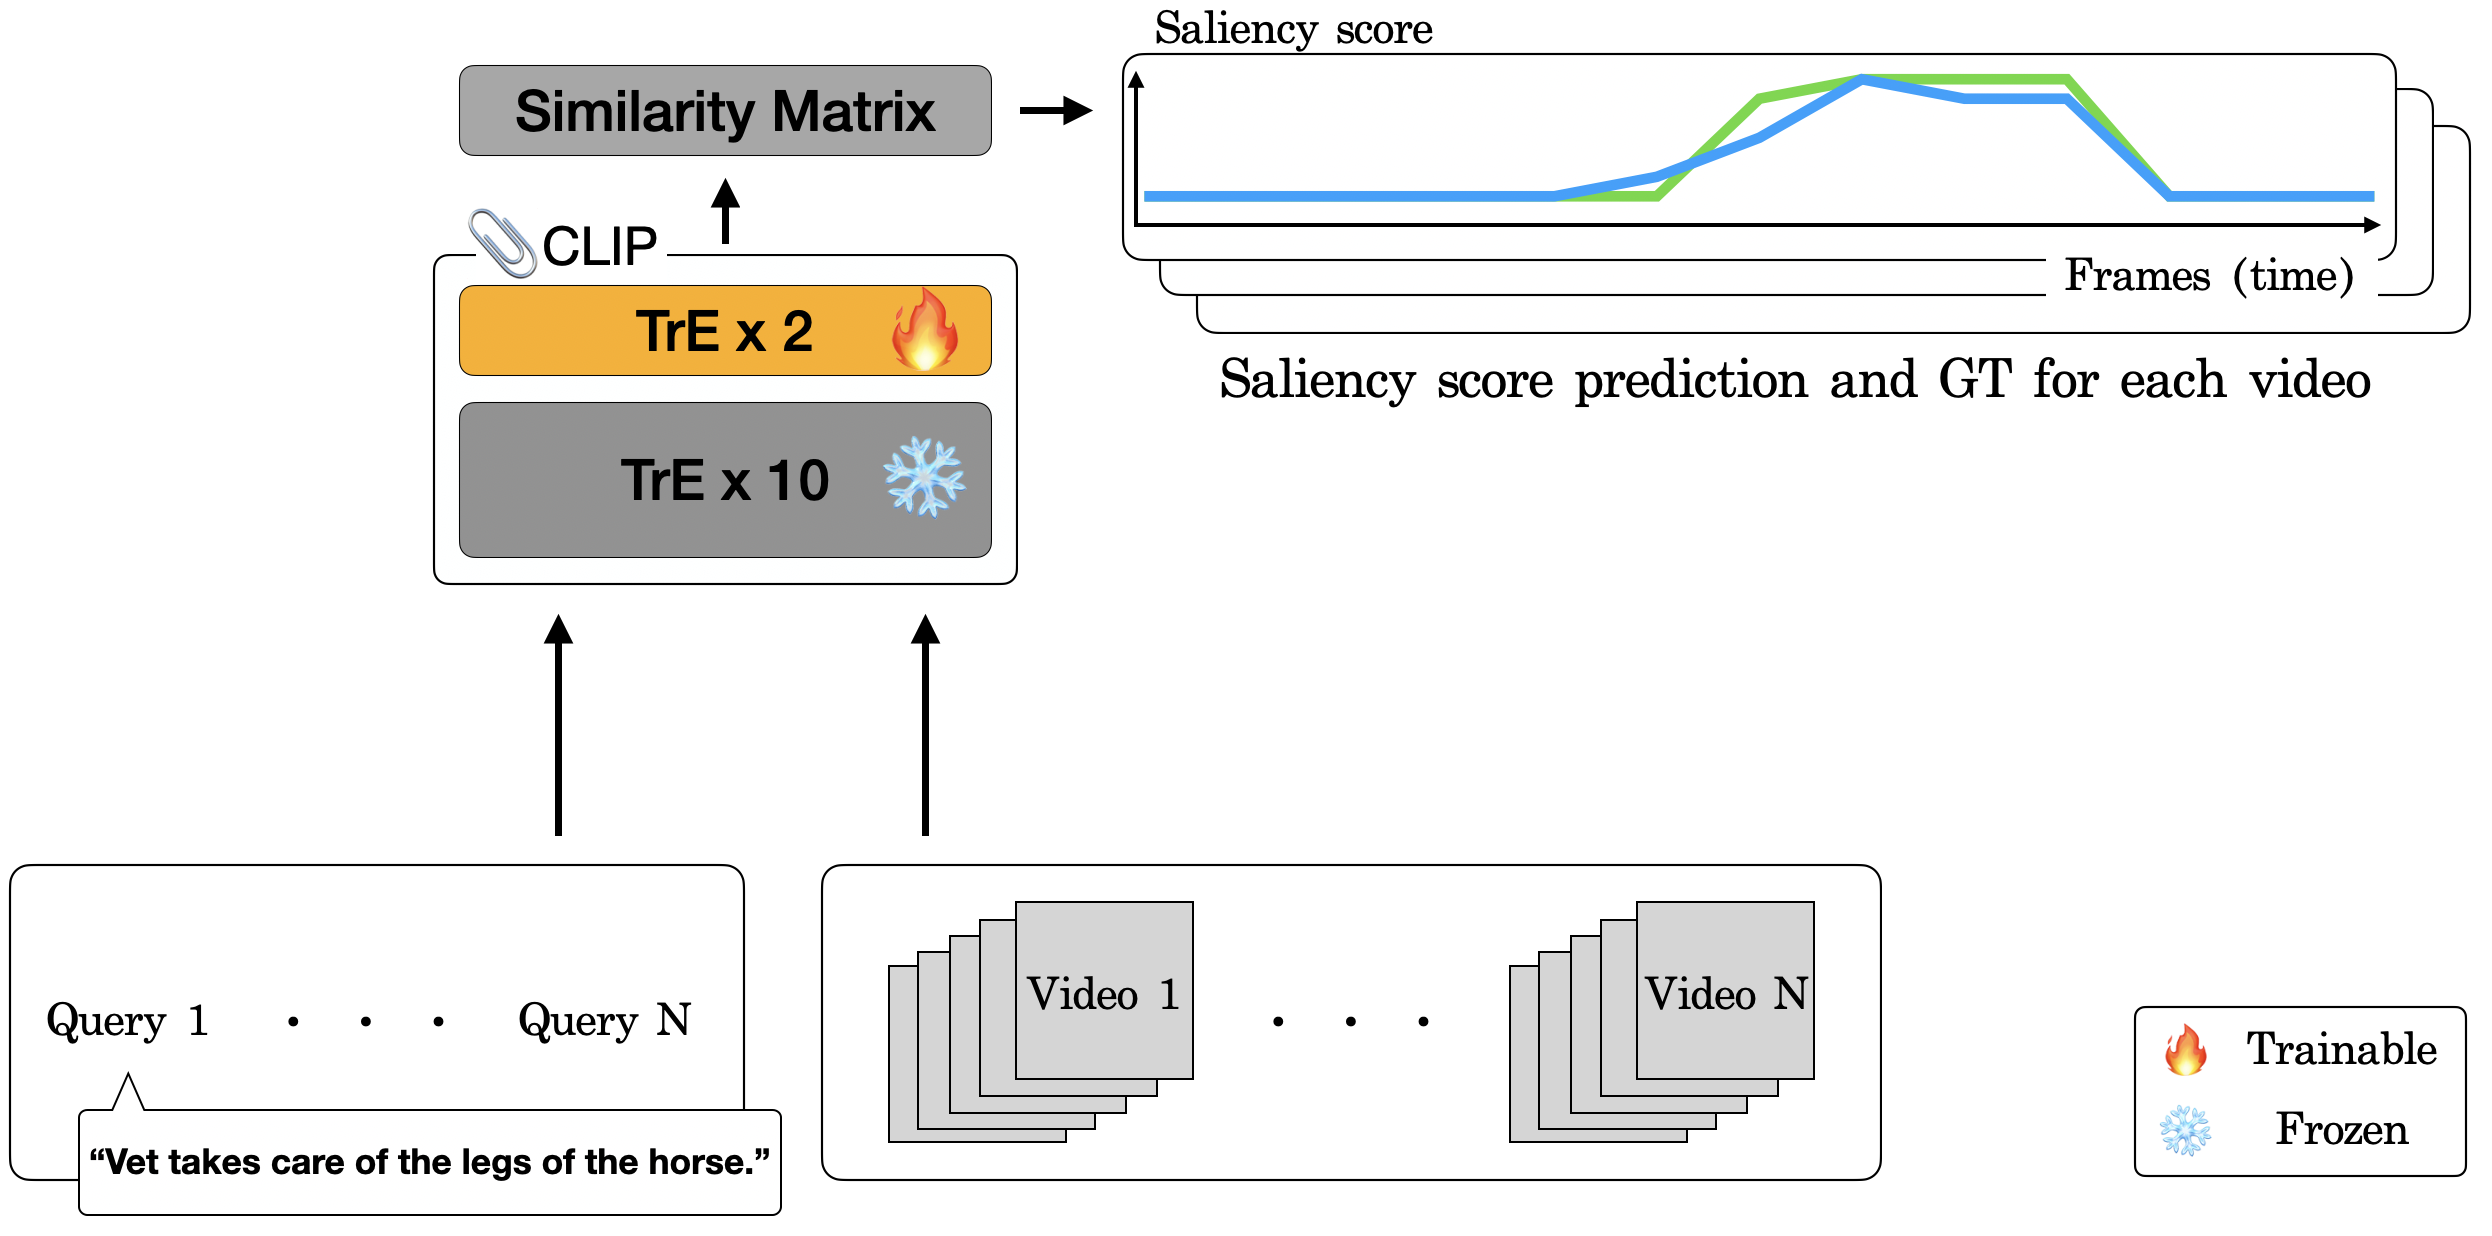
Training
We stack K×N frame–query pairs and supervise with MSE between predicted and ground-truth saliency. Only the last two encoder layers in CLIP receive gradient updates, which preserves the broad pre-trained semantics that make CLIP useful in the first place while specializing the upper layers for the saliency task.
Saliency pooling
At inference, we average predicted saliency over a small temporal window around each frame. This trades off marginal localization sharpness for a meaningful gain in robustness — converting per-frame noise into temporally smoothed scores that better match human-rated highlights.
Main results — QVHighlights
| Method | Val mAP | Val HIT@1 | Test mAP | Test HIT@1 |
|---|---|---|---|---|
| CG-DETR (prior SOTA) | 40.33 | — | 40.33 | — |
| HL-CLIP-2 | 40.00 | — | — | — |
| HL-CLIP-2 + Saliency Pooling | 42.40 | 72.42 | 41.94 | 70.60 |
Saliency pooling alone contributes +2.40 mAP at validation — the design choice that turned the approach into SOTA.
Limitation
HL-CLIP is detector-free by design. It identifies salient moments without localizing precise start/end times — i.e., it solves highlight detection but not full moment retrieval. Combining HL-CLIP scores with a lightweight span head is a natural extension.
Citation
@inproceedings{han2024hlclip,
  title     = {Unleash the Potential of CLIP for Video Highlight Detection},
  author    = {Han, Donghoon and Seo, Seunghyeon and Park, Eunhwan and Nam, SeongUk and Kwak, Nojun},
  booktitle = {CVPR Workshop on Efficient Large Vision Models (ELVM)},
  year      = {2024}
}